Debugging Legacy Interfaces Without Rewriting Them
When an older interface fails, replacing it can hide the cause. A practical method for reproducing the bug, tracing CSS and behavior, and verifying a contained repair.
On this page
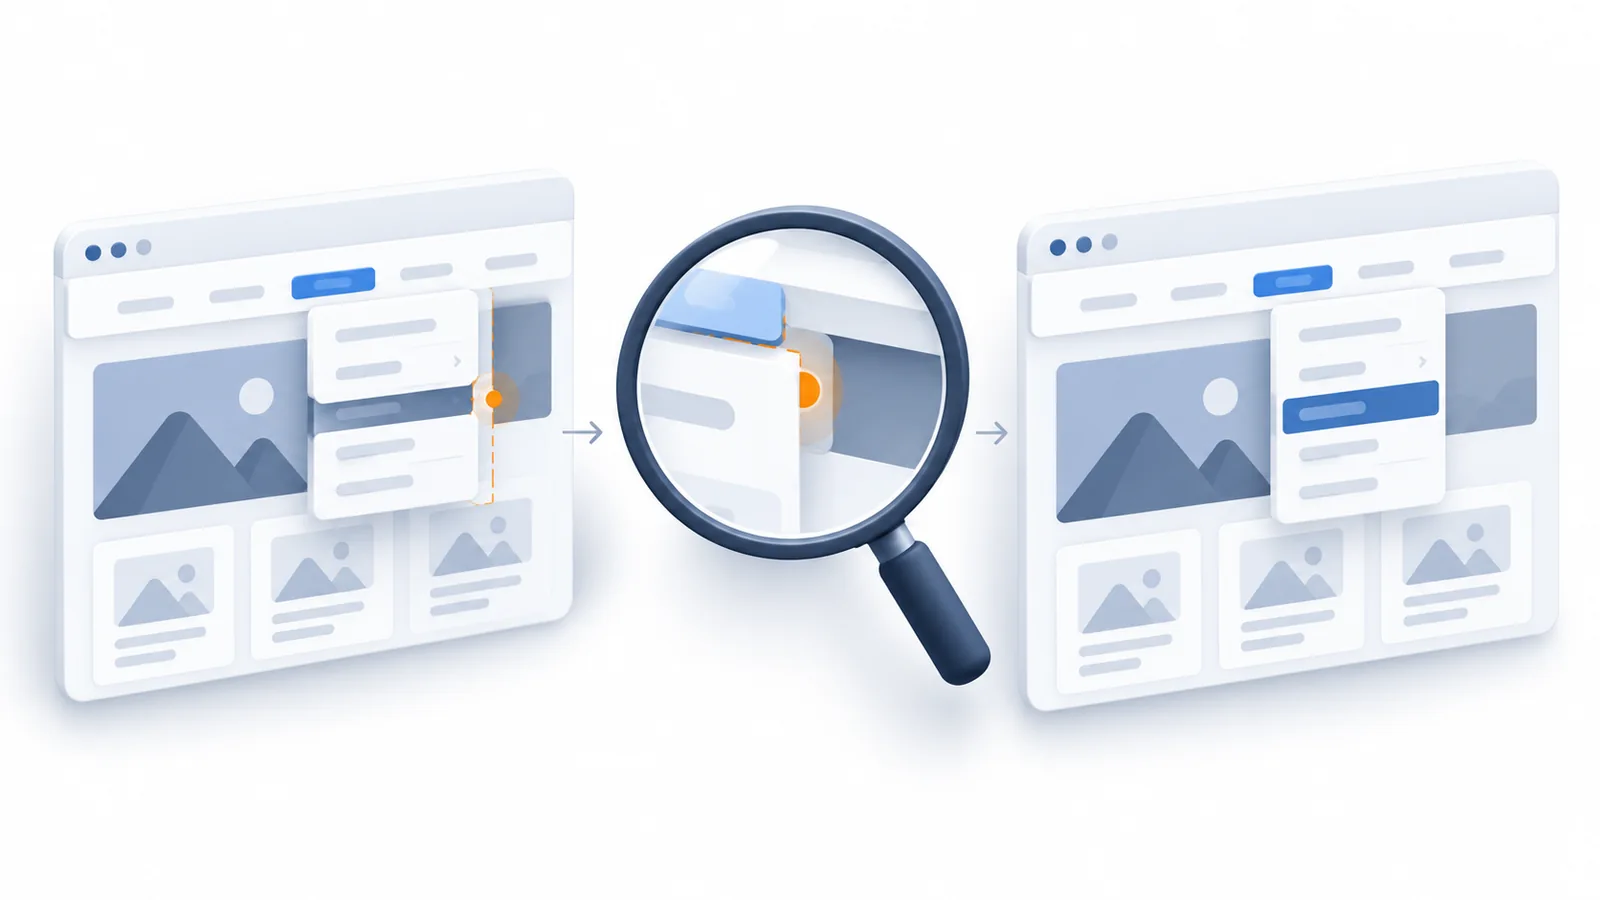
A product page looks correct during desktop review. On a narrow screen, its delivery-options menu overlaps the purchase controls after the visitor opens it for a second time. The issue is reported as “the old CSS is broken.” A quick fix adds a wider selector and a new spacing override. The screenshot looks better, but the same problem appears on another product template.
This is an illustrative debugging scenario, not a report of a specific client incident or a repair I claim to have completed. It reflects a general challenge of mature frontends: the visible defect may be small, but the responsible behavior can be shared across old templates, new layouts, scripts, content variations and deployment combinations.
My work on established e-commerce frontends has made compatibility a practical engineering concern. The useful question is not “how quickly could this page be rebuilt?” It is “what actually caused the failure, which existing contract must remain intact, and what is the smallest change that we can verify?”
Capture a failure, not a description of a feeling
“The dropdown is broken on mobile” is not yet a testable report. A reproduction describes the page variant, relevant data, viewport, browser, starting state, exact interactions and observed result. For this example: use a narrow viewport, load the legacy product template with a long delivery label, choose the pickup option, close the menu, reopen it, then observe whether the open panel covers an actionable purchase control. Note whether the same steps work on the redesigned page.
One detail can change the diagnosis: the first open works, but the second does not. That makes repeated initialization, stale state or a class left behind by an interaction plausible alongside pure layout causes. The long label matters because text wrapping can expose a size constraint not visible in a short fixture. Neither clue proves a root cause; both make the investigation falsifiable.
I would record a compact baseline: the affected template, the route or local fixture, the build revision, browser and viewport, the sequence of actions, the expected behavior, the actual result, and one screenshot or short recording. If the bug involves a network-dependent transition, preserve the relevant request and response metadata without recording customer secrets. The point is a reliable replay, not an impressive bug report.
Separate layout, behavior and data before changing code
A dropdown can look wrong for different reasons. The panel may have the wrong width because its parent cannot shrink. It may be positioned relative to the wrong container. A previous handler may have left an “open” class after closing. An API response may have changed the available options while the interface retained an earlier selection. A mixed release may load newer styling against older markup.
Each explanation implies a different remedy. Changing padding cannot repair a duplicate event handler. Rewriting the component cannot fix a stale asset being served from a cache unless the delivery issue is also addressed. Replacing the entire page before identifying the failing boundary makes the regression harder to contain and often destroys useful evidence.
| Observed symptom | Competing explanations | Best next check |
|---|---|---|
| Only after reopen | Stale state; duplicate listeners | Trace events and classes |
| Only with long text | Wrapping; flex minimum width | Inspect computed geometry |
| Only one template | Markup or shared-asset mismatch | Compare DOM and CSS/JS |
| Only after deployment | Cached assets; environment drift | Compare versions and requests |
Investigate in layers. First inspect the actual DOM after the failing interaction: is the menu where the code expects it, are its state classes correct, and are duplicated nodes present? Next inspect computed layout: the panel’s containing block, width, max-width, overflow, flex sizing and the rules actually winning the cascade. Then examine the event lifecycle and relevant network requests. Finally compare the affected template with an unaffected variant under the same assets.
Use computed styles, not guesses about CSS specificity
The CSS cascade is not simply “the most specific selector wins.” Origin, importance, cascade layers, scope, specificity and source order all affect which declaration applies. MDN’s guide to CSS cascading and inheritance explains the decision process, while Chrome DevTools’ Styles and Computed views show which rules match a real element. Inspect the winning declaration and its source before adding another override.
Suppose the panel’s width is set to 100%, but the flex child that contains it is refusing to shrink. A new fixed width may make the current screenshot pass and create horizontal overflow at another viewport. Testing the parent’s sizing constraint and the content’s minimum width would distinguish that hypothesis. The appropriate fix might belong on the parent or the component’s layout contract, not on the menu panel itself.
A temporary change in DevTools is useful as an experiment; it is not evidence that the whole regression is solved. Reapply the change in the source, rebuild with the actual pipeline, and test the same input conditions rather than trusting a local override that might mask a different rule.
Trace the interaction when the first attempt differs from the second
If reopening causes the defect, watch what changes between the first and second activation. Does one click trigger two callbacks? Is the component initialized more than once after a partial navigation? Does the document retain an overlay or an aria-expanded value inconsistent with the visible state? Are event listeners attached to nodes that are later replaced?
Instrument only enough to answer the question. A small count of open and close events, a snapshot of the relevant DOM attributes, and a trace of the request associated with selecting an option can differentiate competing causes. Playwright’s Trace Viewer can help inspect the sequence of a reproduced automated failure, including browser actions and snapshots; the trace is useful evidence, not a substitute for deciding which behavior the component should guarantee.
When an asynchronous result affects the interface, inspect response status and ordering as well. The Fetch API does not reject its promise merely because the server returned an HTTP error status; code must inspect the response. A loading indicator that disappears while the application silently ignores an error can look like a frontend rendering problem even when the failed request is the decisive event.
Do not assume an old interface is disposable
“Legacy” usually identifies an implementation or generation, not the business importance of the people using it. An older product template may still support valid purchasing journeys, and a redesign may coexist with it for weeks or months. A change that is correct only in the new template can still be a regression if the shared stylesheet or script reaches the old one.
Before modifying shared code, identify who consumes it. Search the component imports and style entry points; examine which markup variants are generated; confirm how assets are versioned and released. Ask whether the deployment can expose old HTML with new assets, and if so for how long. Not every system has this mixed-version risk, so verify the actual delivery architecture instead of inventing a worst case.
This is the boundary between debugging and release-impact analysis. The related article The Release Risk Hidden Inside a Small Frontend Change addresses how wide a change can reach. Here the emphasis is earlier and narrower: obtaining reliable evidence about why a specific interface fails before deciding what to change.
Prefer a contained repair, but give a rewrite a fair test
A targeted repair is attractive when the failure has one demonstrable cause, existing behavior is stable, and the fix can be isolated behind a reliable variant or component boundary. It is a poor choice if several incompatible state models are being forced through the same lifecycle, or if repeated overrides make every subsequent change less predictable.
A rewrite can be justified, but its burden of proof is larger than producing a cleaner component in isolation. The replacement must preserve business rules, keyboard access, responsive behavior, analytics or operational events where relevant, and all legitimate consumer states. It also needs migration sequencing and a rollback story. If the old component can be repaired and retired on a known schedule, a narrow patch plus planned migration may be the lower-risk decision.
I find it useful to ask: could someone unfamiliar with the code explain why this repair cannot affect the other variant? If not, the scope is still ambiguous. Conversely, if the defect is rooted in fundamentally incompatible interactions and the variants have independent futures, explicit separation may be safer than one more conditional.
Verify the symptom, the contract and the release combination
After the fix, replay the original steps first. The menu should open, close and reopen without overlaying the purchase controls. Test short and long labels, the narrowest supported viewport, keyboard activation, focus visibility and the selected value after state changes. WCAG’s keyboard and focus criteria are useful anchors when the repaired control is interactive; a visual comparison alone cannot prove it remains operable.
Then test at least one unaffected consumer: an older product page and a redesigned page if they share the changed asset or behavior. Compare the real states that matter, not every page that happens to import the same CSS file. If the release can produce older markup with newer assets, include that combination. If it cannot, explain why that state is excluded.
A regression test should make the failure detectable rather than encode one incidental CSS measurement. Checking that the option can be selected, that the control remains visible and that the active state is correct usually survives future visual refinement better than asserting an arbitrary pixel position. Use visual snapshots when the geometry itself is the contract, and keep their limitations in mind.
A short evidence-to-action record
After reproducing the issue, a useful handoff can fit into six lines: observed failure; minimal reproduction; root-cause evidence; affected consumers; proposed change; verification and unresolved risk. If the cause remains uncertain, say so and record the next test. A team should be able to distinguish “we patched the visible overlap” from “we identified and verified the source of the overlap.”
The payoff is a smaller, more reliable decision
Old interfaces do not always need defending, and they do not automatically need rebuilding. Their maintenance becomes tractable when engineers treat observable behavior as evidence, inspect the system boundaries that produce it, and resist replacing one unverified explanation with another.
In the hypothetical dropdown case, the successful outcome is not the elegance of a CSS diff. It is a repair backed by a reproducible failure, a demonstrated cause, a documented compatibility boundary and checks capable of catching the problem again. That discipline makes the next change easier, even when the next change eventually is a rewrite.
The Release Risk Hidden Inside a Small Frontend Change
How to evaluate impact when a new interface must coexist with an older one
Read article
Testing Shared UI Components Without Testing Every Page Twice
Reusing a UI component does not mean testing every page identically. A practical coverage map shows which behaviors belong in component, integration and browser tests.
Read article